351sources crawled
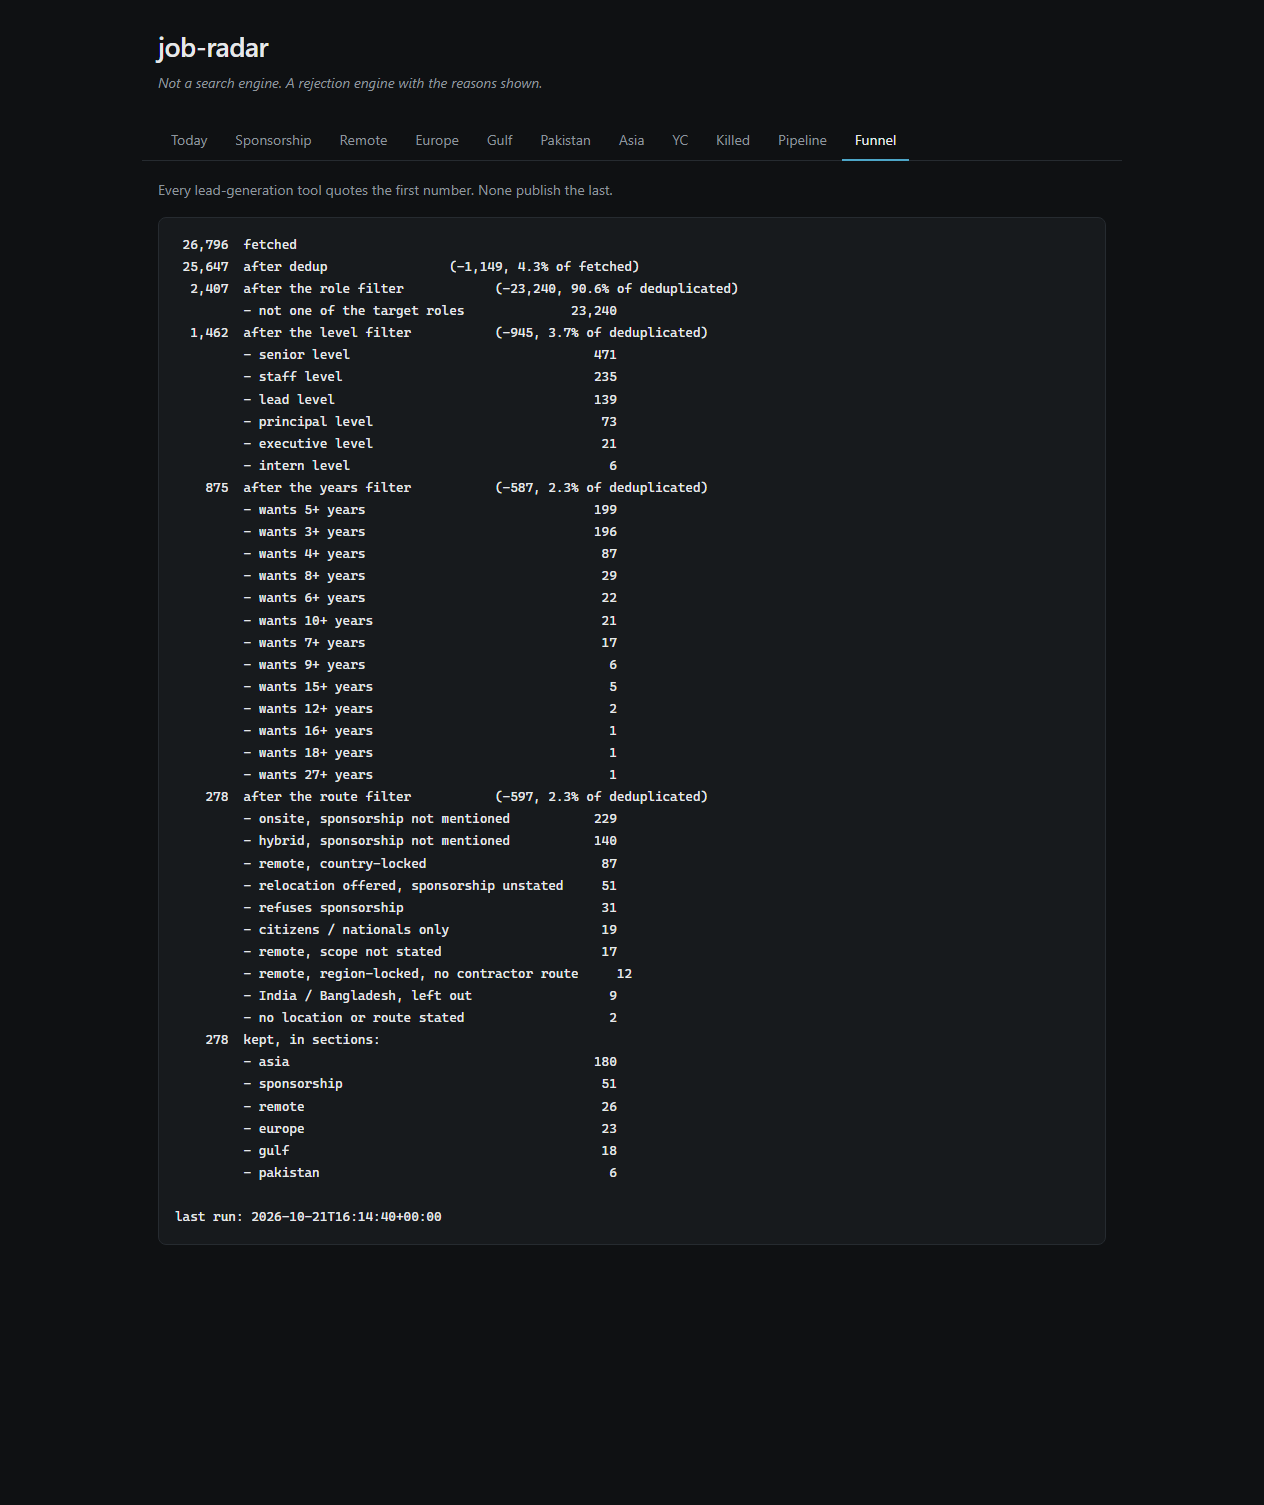
26,796postings read
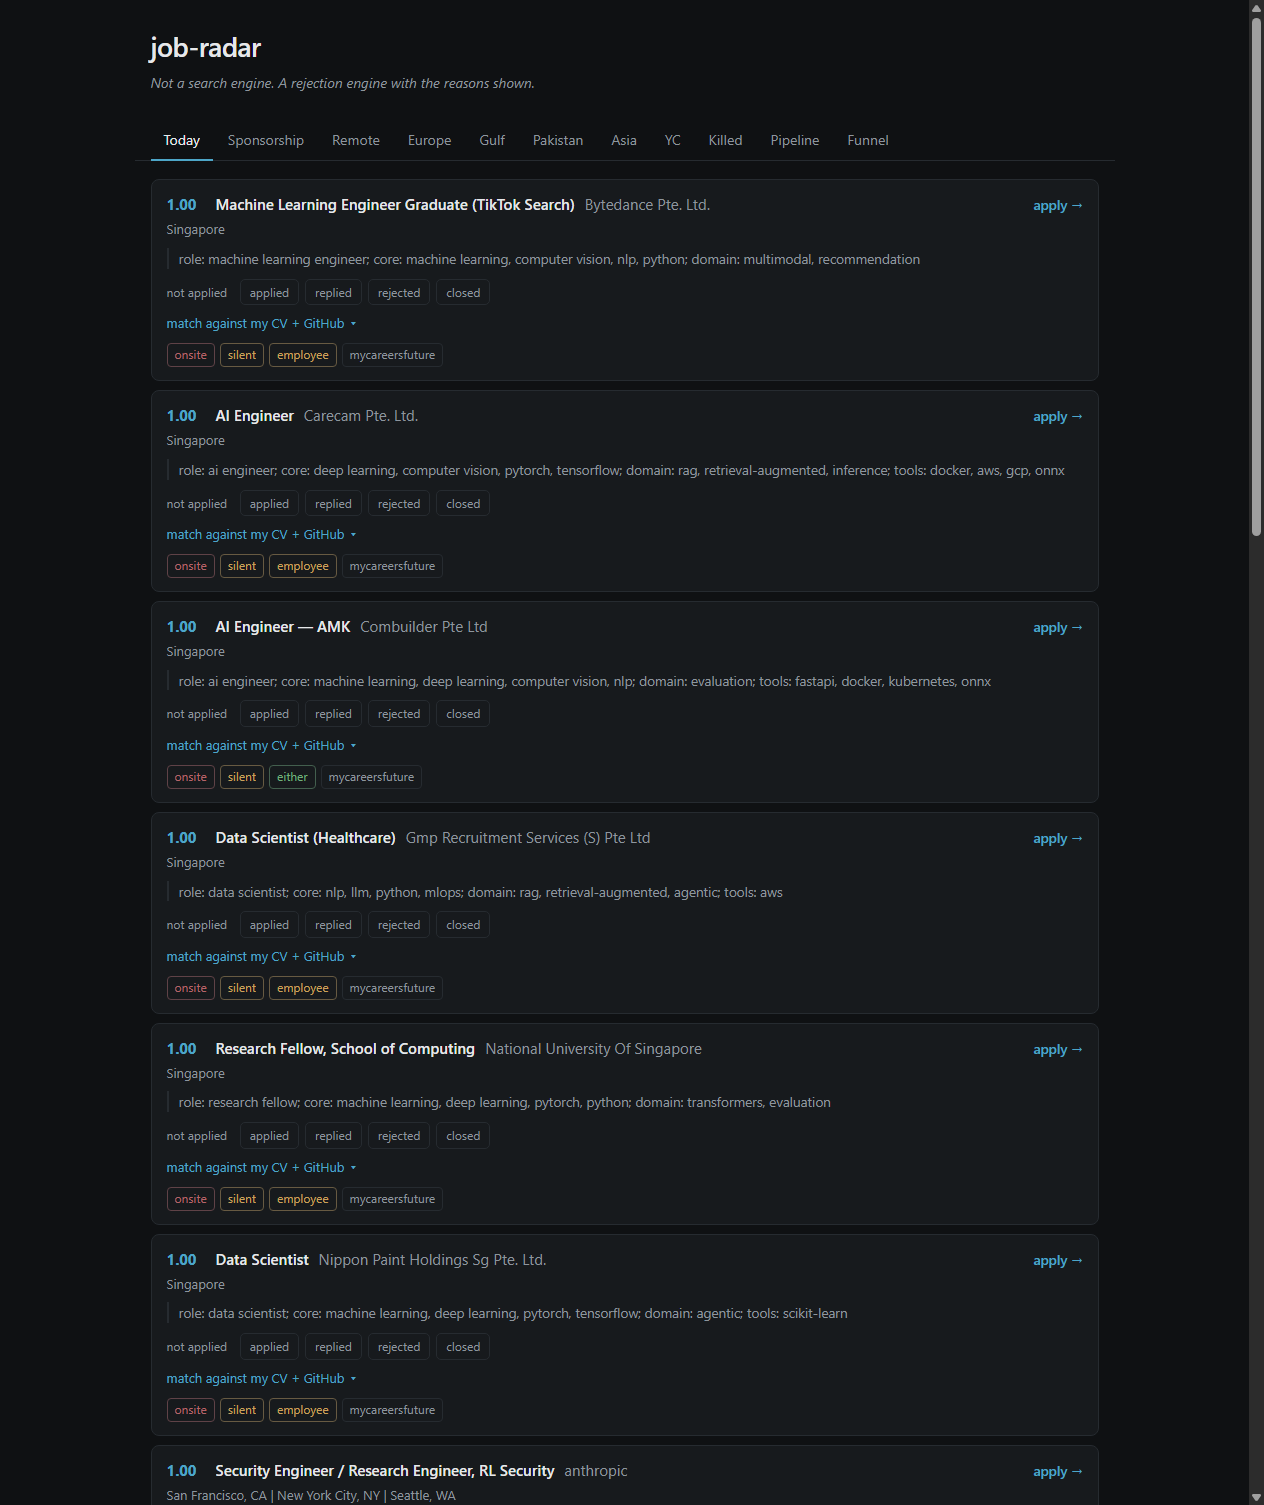
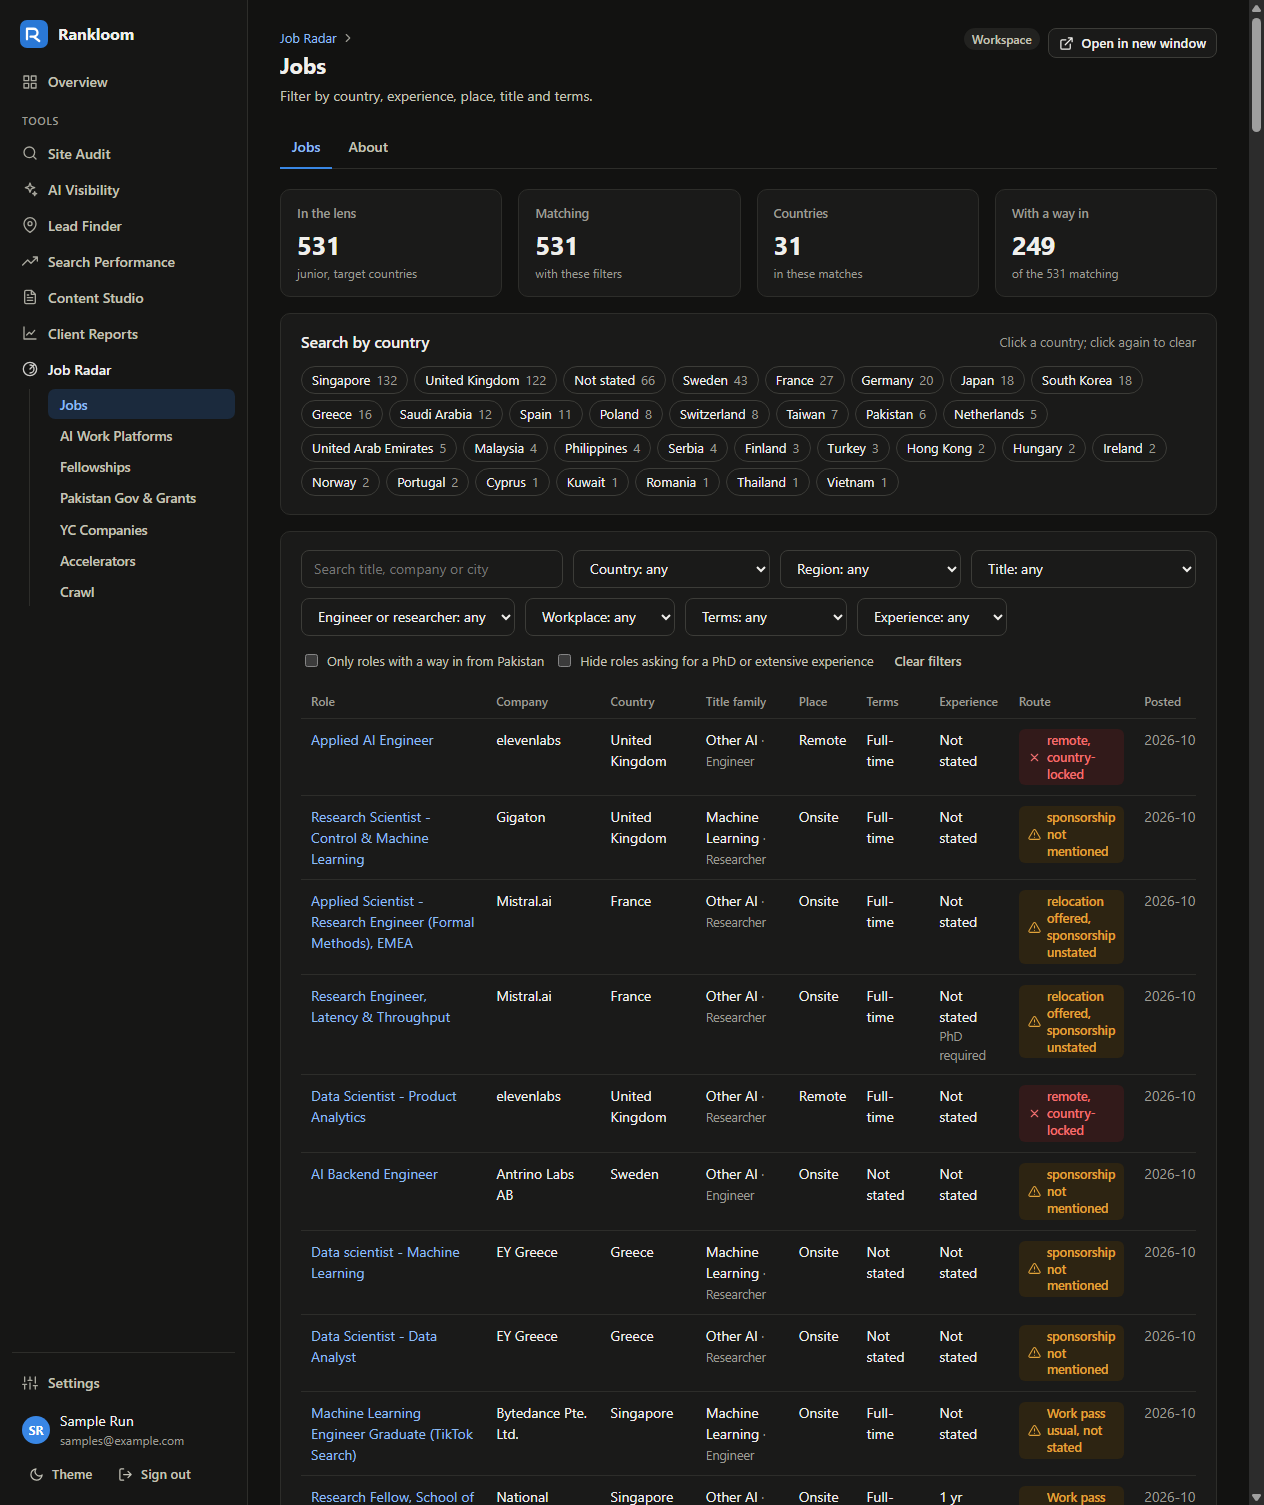
531junior AI roles in 31 countries
249with a way in from Pakistan
332automated tests
Demo
What it does
- Polite crawlerrobots.txt obeyed, one request at a time per host, every answer cached.
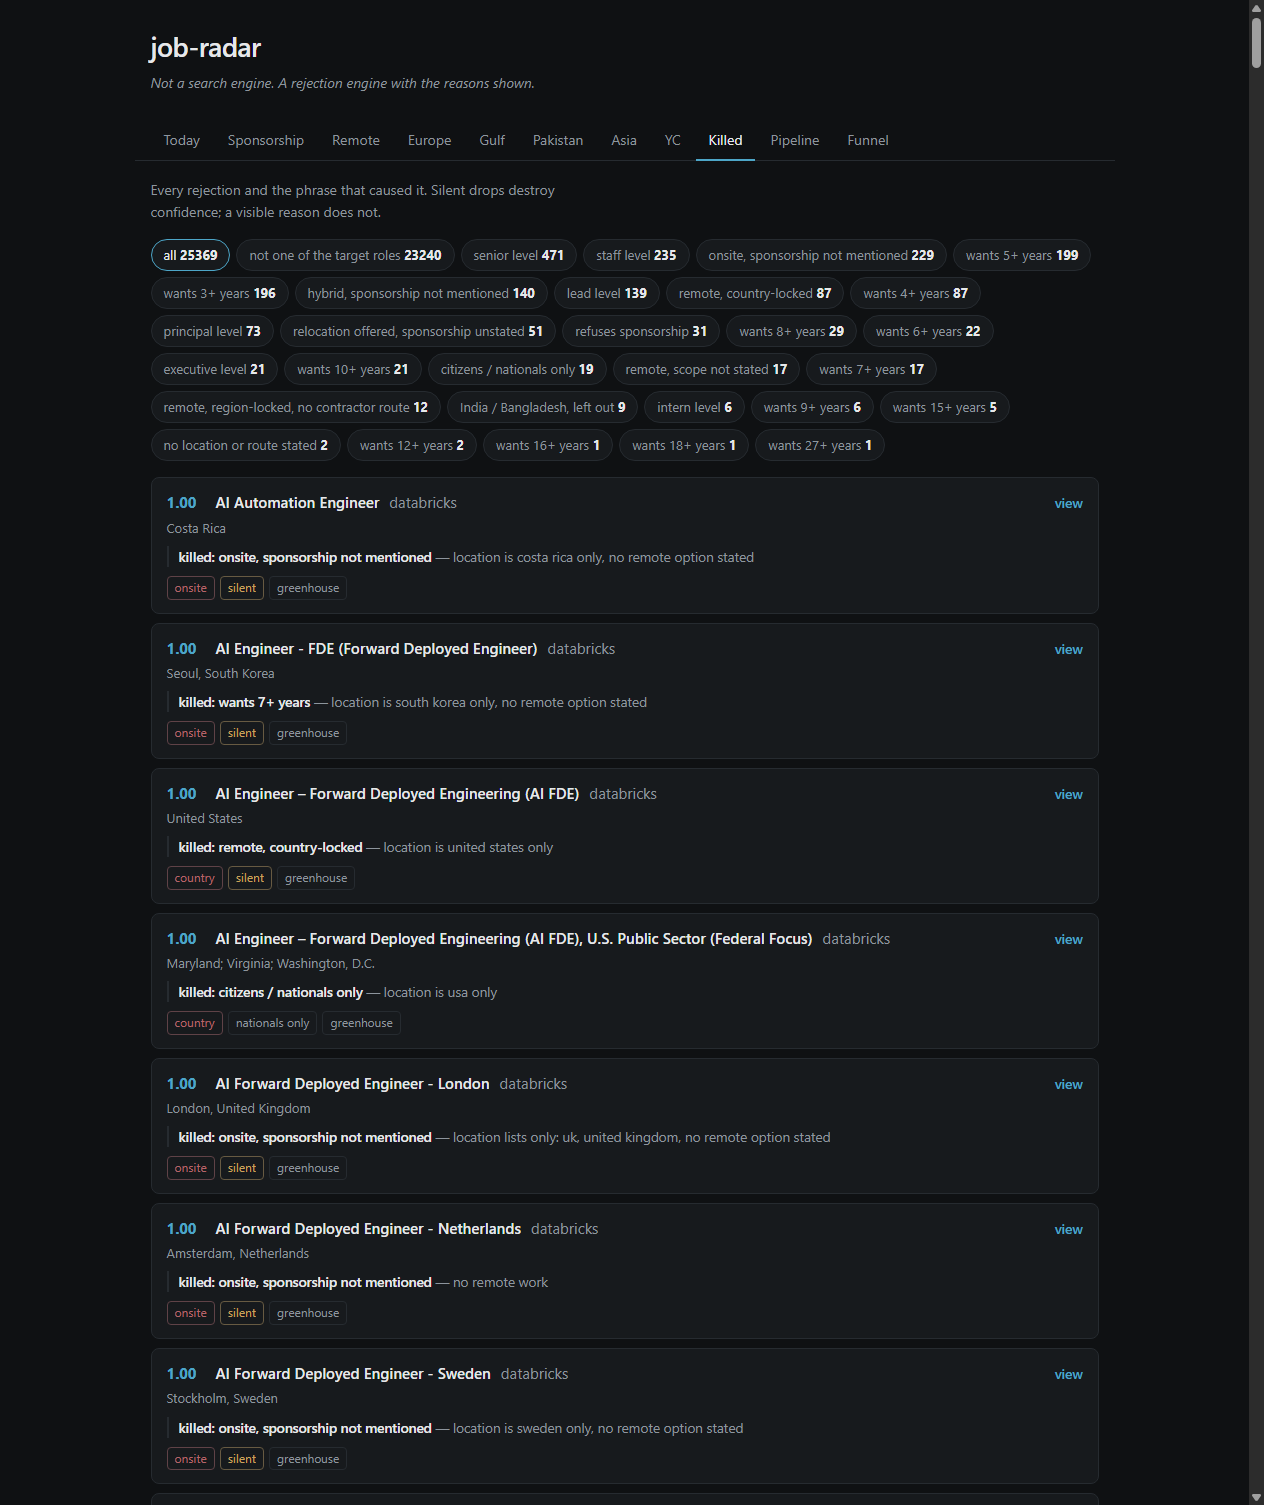
- Rejection engineEvery removed posting is kept with the rule and phrase that removed it.
- Route badgesSponsorship, remote open from abroad, a usual work pass, or closed.
- Junior onlySenior titles and more than 2 years asked are removed; PhD asks are flagged.
- YC companies2,481 companies over 15 batches, with LinkedIn read from YC's own pages.
- Portfolios6,255 companies from 7 accelerator and investor portfolios, 3,875 AI postings.
- DirectoryAI work platforms, paid fellowships and grants, with who can apply.
Input and output
The latest run, from job boards to the dashboard.
| Tool | Input | Output |
|---|---|---|
| Crawl | 351 sources | 26,796 postings read |
| Duplicates | 26,796 postings | 25,647 left |
| Title gate | Target AI families only | 2,407 left |
| Level and years | No senior titles, at most 2 years | 875 left |
| Route | A way in from Pakistan | 278 routed; 531 roles in the country lens |
| One posting | 'AI Tutor - Croatian', remote worldwide, no sponsorship | AI data work, small contract, route: remote |
How a request flows
- Cache check
- robots.txt
- Per-host pacing
- Board JSON
- Duplicates
- Title, level, years
- Route from Pakistan
- SQLite
- Dashboard
Screens
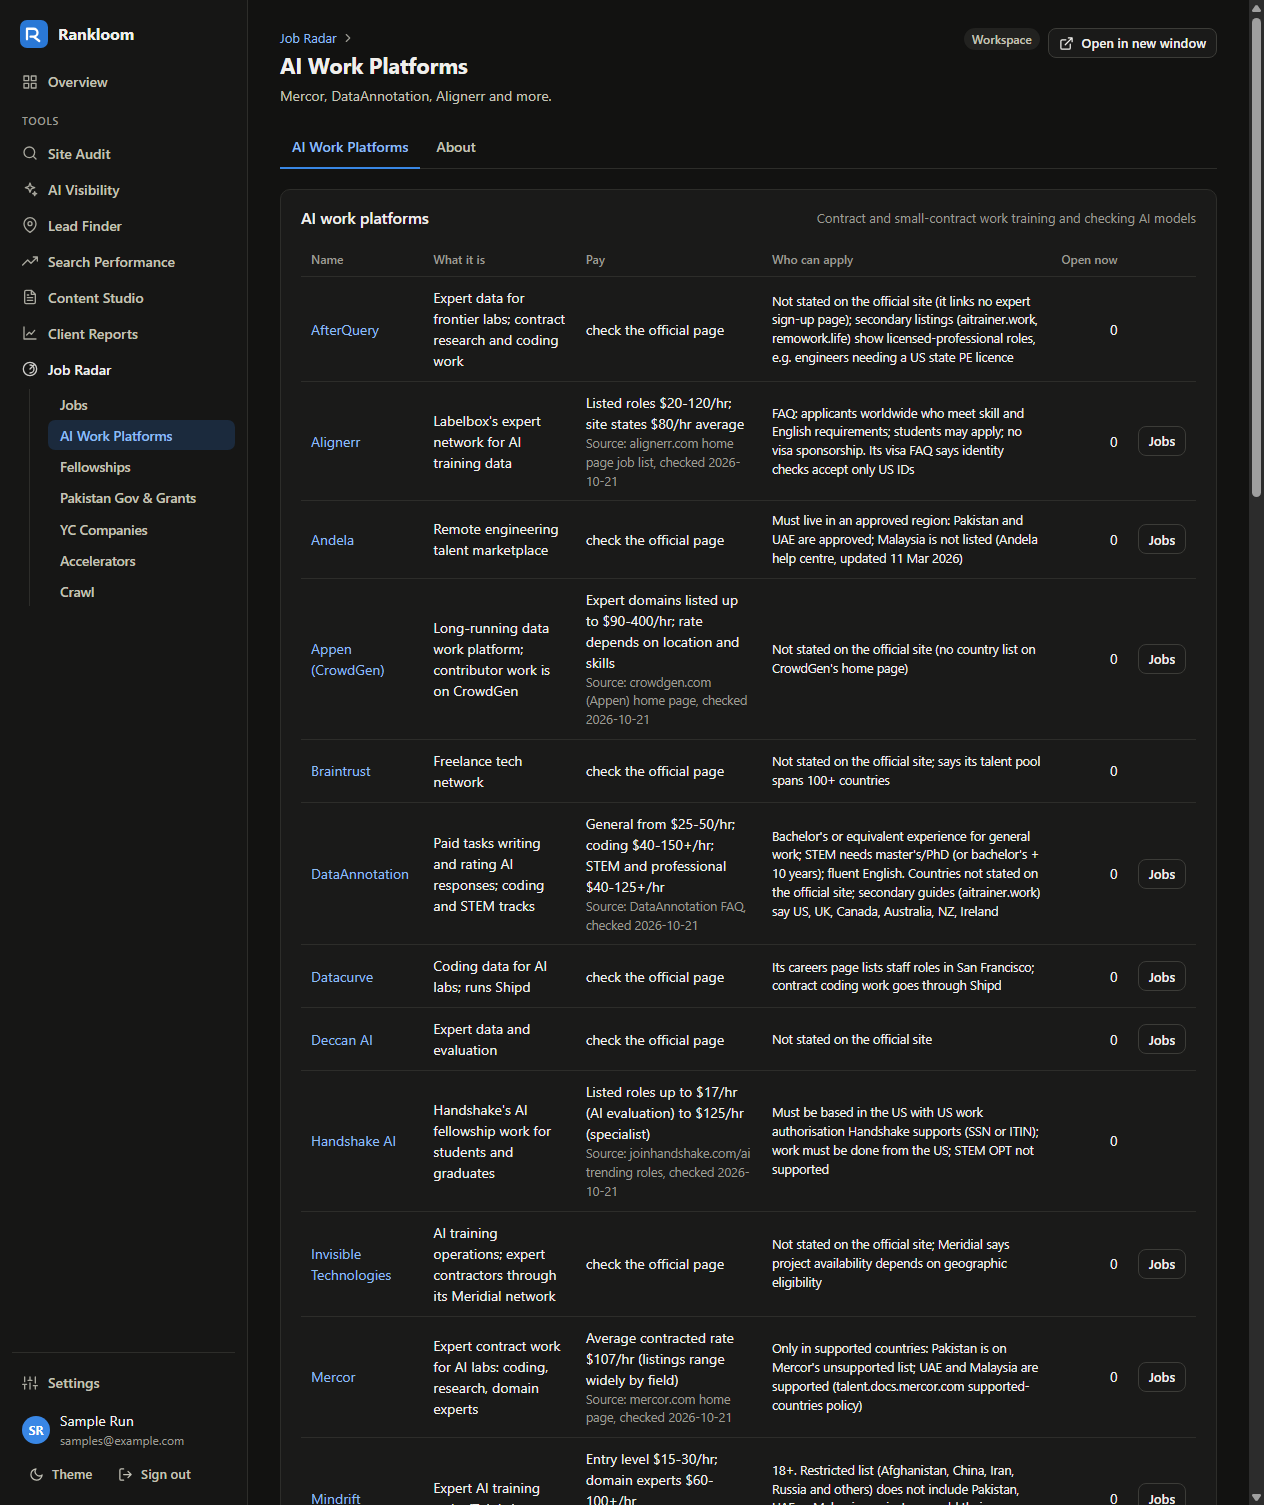
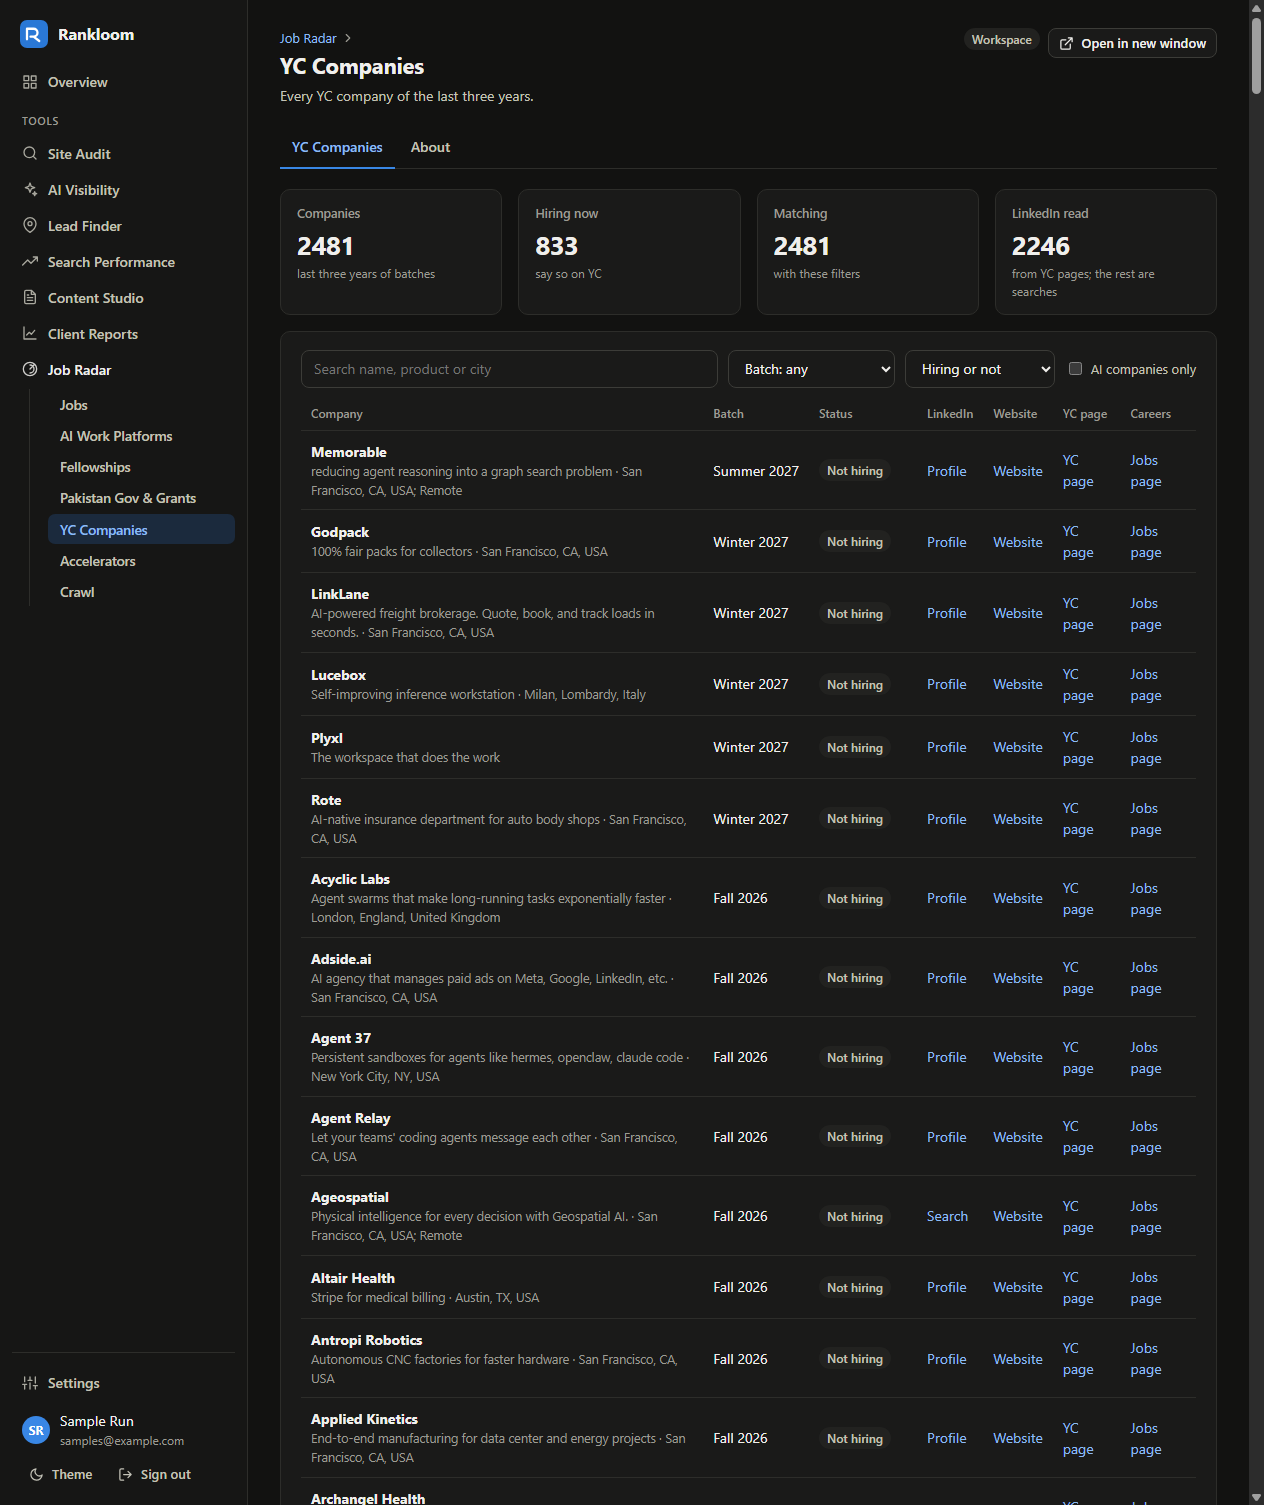
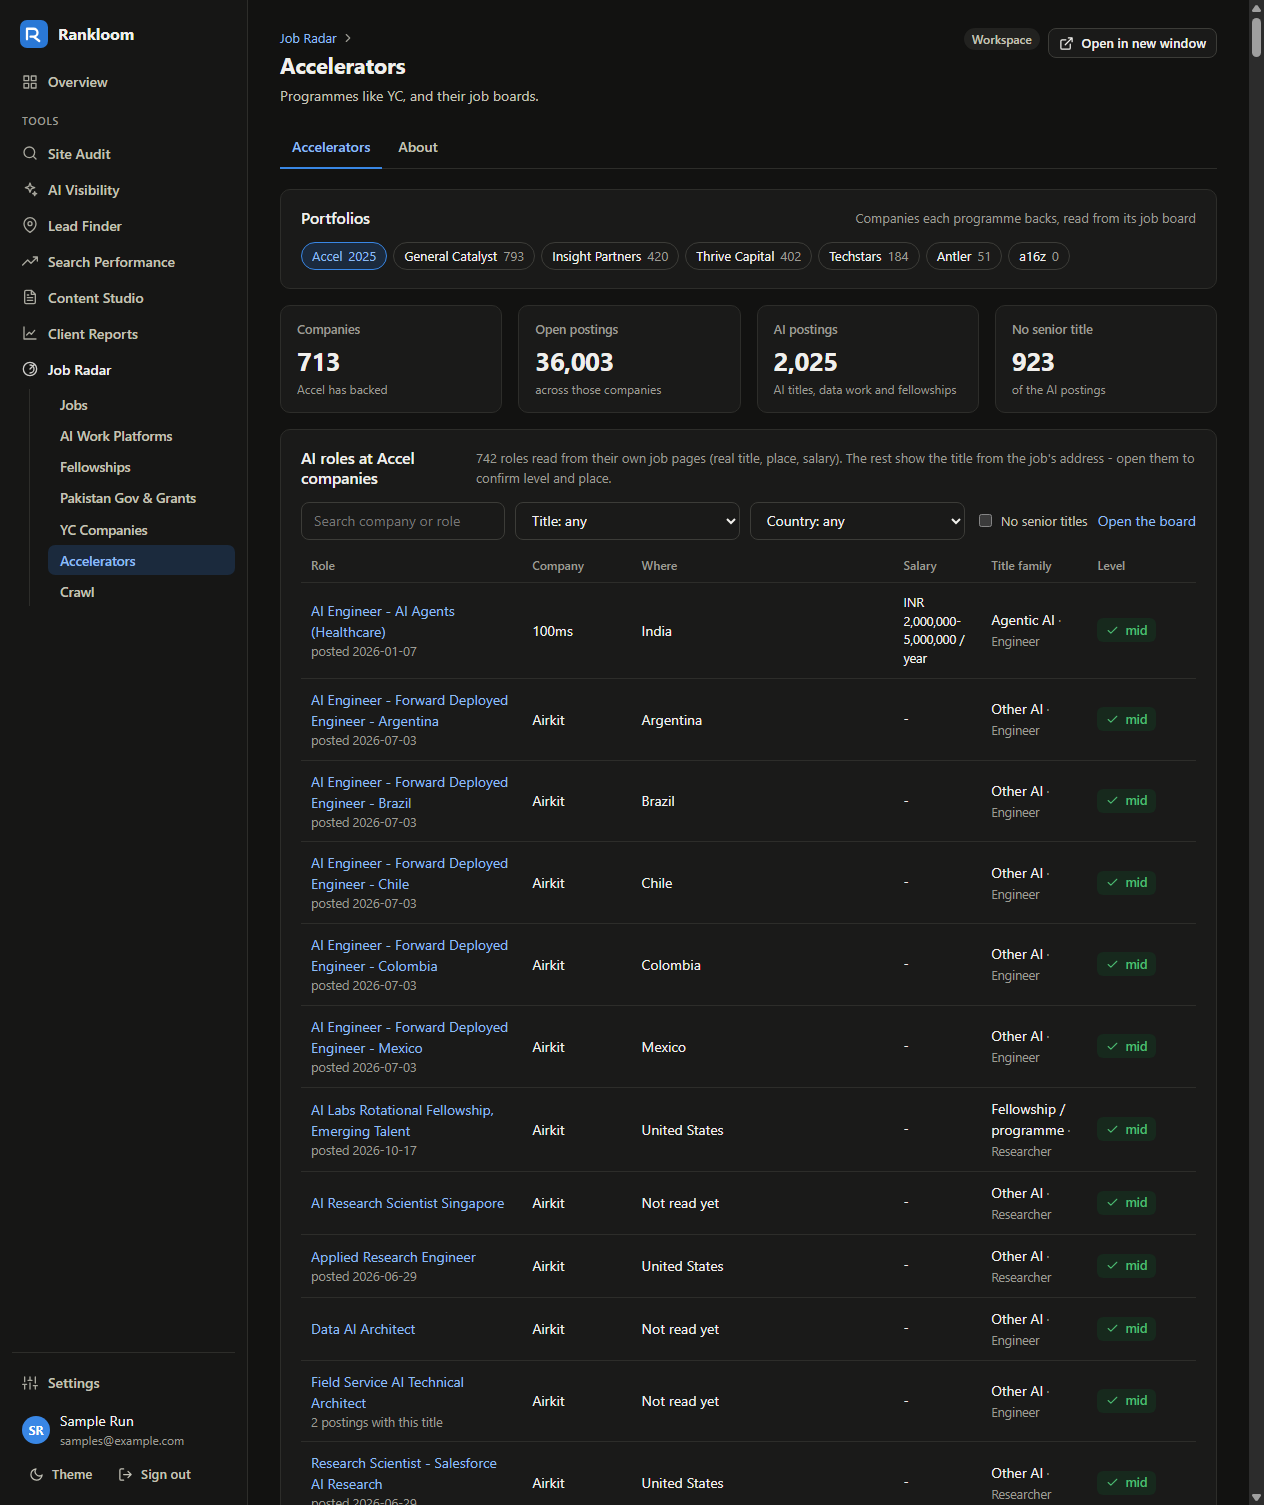
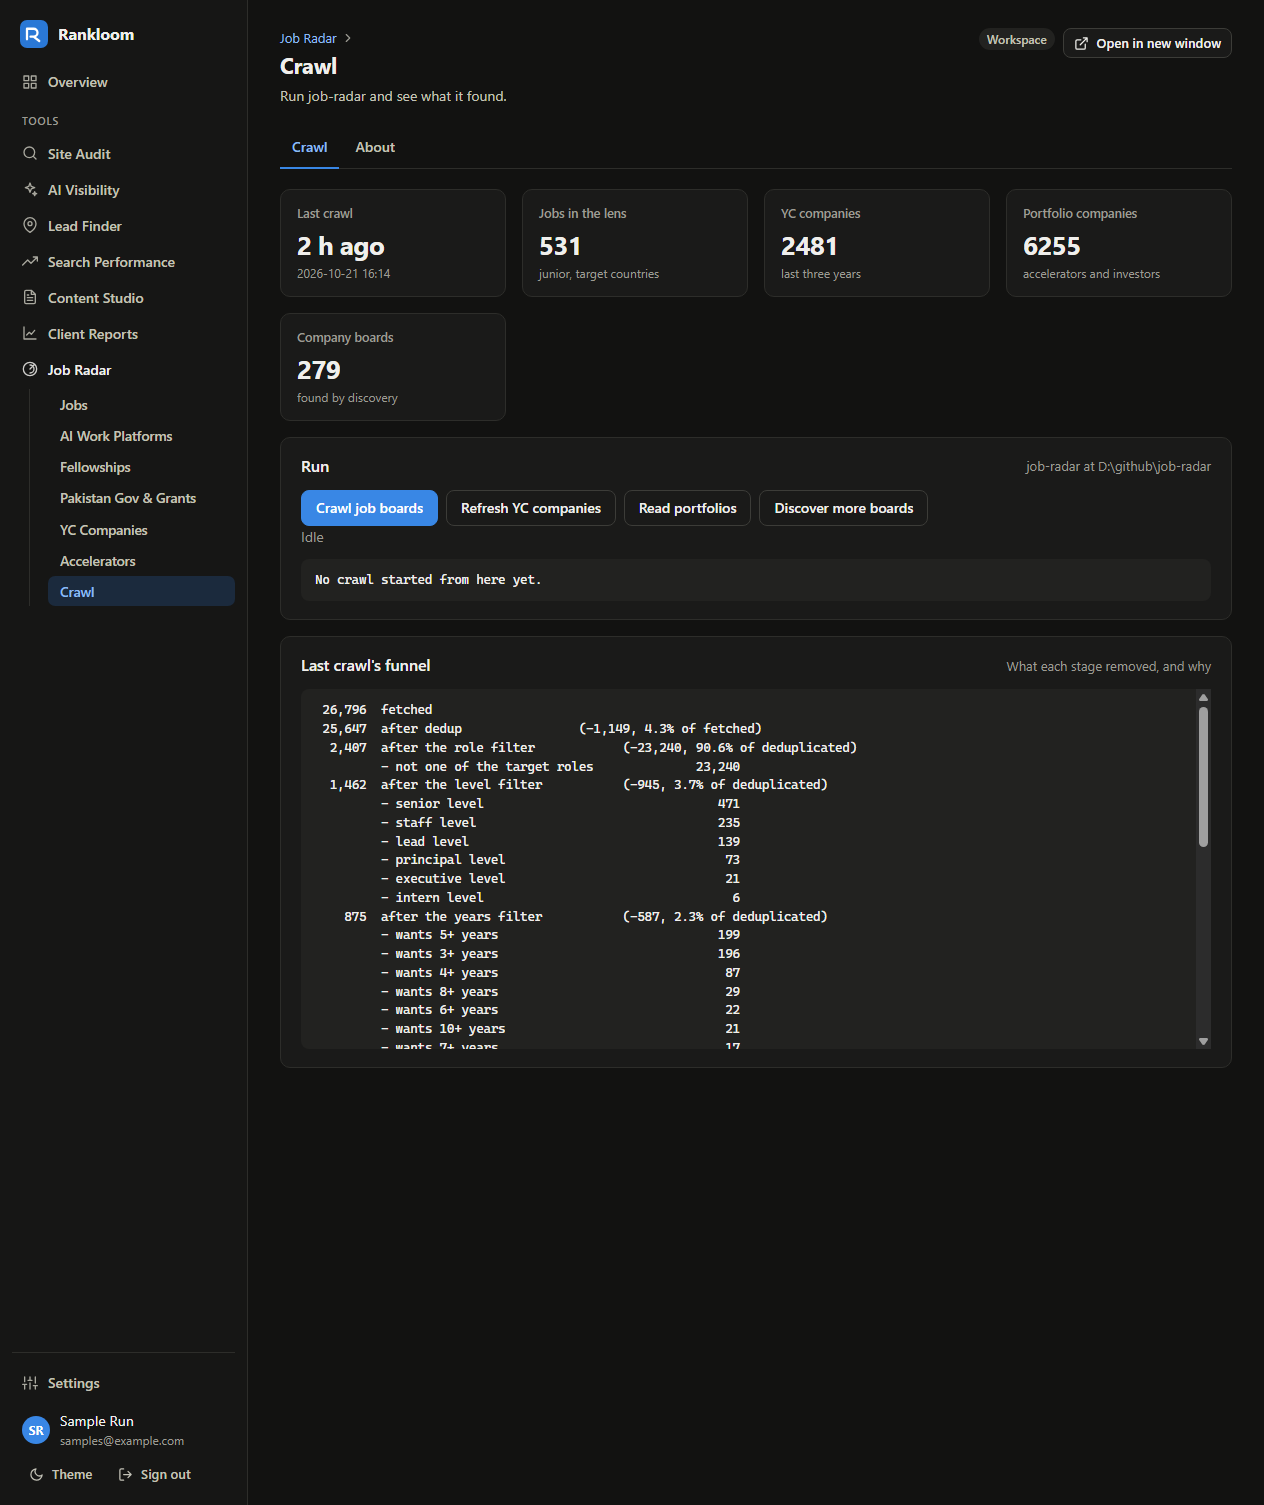
Built with
| Crawler | Python, urllib with robots.txt parsing, gzipped on-disk cache |
| Rules | Plain Python filters for titles, levels, workplace, authorisation and places |
| Storage | SQLite |
| Dashboard | FastAPI with uvicorn, plain HTML, CSS and JavaScript |
| Quality | pytest with real posting wording as fixtures, offline cache replays |